

Software vulnerabilities hidden in complex systems of interconnected machines, representing how vulnerabilities arise and go unnoticed during software development and security testing.
Software vulnerabilities often begin as ordinary engineering mistakes: an unchecked input, an incorrect permission decision or an assumption that another component will enforce a rule. The application may still work perfectly for its intended users. The weakness appears only when someone supplies unexpected data, crosses an overlooked trust boundary or combines features in a way the developers never anticipated.
That gap between “works correctly” and “resists misuse” explains why security flaws can survive code reviews, automated tests and years of production use. Understanding the gap is more useful than assuming every incident comes from obviously careless programming.
A working feature can still contain a security flaw
A software bug is a defect in how a program behaves. A security flaw is a weakness that can let someone violate an intended protection, such as accessing another customer’s records or executing unauthorized code. Not every bug creates that opportunity.
Consider an invoice download feature. Testing might confirm that a signed-in customer can retrieve an invoice. But if the server checks only whether someone is logged in, rather than whether that person owns the requested invoice, the feature remains insecure despite passing its basic tests.
The distinction matters because an attacker’s objective differs from a legitimate user’s objective. The user wants the expected workflow to succeed; the attacker looks for an unintended capability. Our guide to threats, weaknesses, risks and exploits explains how these concepts connect without treating them as interchangeable.
How software vulnerabilities arise
Most security defects develop where software accepts input, makes a trust decision or relies on another component. Several recurring mechanisms explain how those decisions go wrong.
Input reaches a dangerous operation without adequate controls
Applications constantly process data they do not control: uploaded documents, API parameters, network messages and database records originating elsewhere. Problems arise when that data reaches an operation with stronger privileges or different interpretation rules.
For example, constructing a database query by combining commands with untrusted text can let input change the meaning of the query. Parameterized queries address that mechanism by separating data from executable query structure.
Memory-handling errors follow a different path. A program might trust a supplied length without checking whether the underlying buffer contains that much data. The consequences can include a crash, an unintended memory read or, in some circumstances, code execution. The outcome depends on the defect and its surrounding protections.
Permission checks and business rules are incomplete
Some vulnerabilities arise even when input is well formed and memory handling is correct. The application simply allows an action that the requester should not be permitted to perform.
Authentication establishes identity. Authorization determines what that identity may access or change. A permission check on one webpage does not protect a separate API endpoint unless the server enforces the same rule there.
Business workflows introduce additional problems. A checkout process might validate a discount before an order changes, then fail to validate it again before payment. Concurrent requests can also expose gaps when a check and the action it permits are not handled atomically.
The OWASP Authorization Cheat Sheet recommends validating permissions on every request. That principle helps prevent security from depending on which route a user takes through an application.
Dependencies and deployment choices introduce hidden assumptions
An application inherits behavior from libraries, frameworks, container images and services. A team can write its own code carefully while still shipping a dependency with a serious defect.
Configuration creates another route. A diagnostic endpoint suitable for a restricted development environment may expose sensitive information when deployed publicly. A cloud role intended for one workload may receive permissions broader than that workload needs.
Software vulnerabilities can also become exploitable after the original release because surrounding conditions change. A previously internal service becomes internet-facing, a new integration exposes an old parser or sensitive information begins flowing through an existing feature.
AI-generated code does not remove these risks. It still needs review against the application’s actual trust boundaries, as our explanation of security risks in AI-generated code discusses.
Why ordinary testing misses security defects
Most development checks answer a necessary question: does the software do what its requirements say? Security testing must also ask what else the software allows, including behavior the requirements never mention.
Tests often repeat the developer’s assumptions
If a developer believes an upstream service already validates ownership, they may write both the implementation and its tests around that assumption. The tests then reinforce the mistake rather than challenge it.
Mocks can deepen this blind spot. A simulated identity service may always return valid roles, while the real integration accepts missing claims or interprets them differently. Each component looks correct in isolation, but their interaction weakens the protection.
Good negative tests challenge these assumptions directly: a user from another account requests the same object, a revoked role attempts an action or an earlier workflow step is skipped. These tests examine security rules rather than merely checking whether an endpoint returns a successful response.
Coverage measures execution, not resistance to misuse
High code coverage does not demonstrate the absence of vulnerabilities. It shows that tests executed particular code, not that they explored every meaningful input, identity, application state or timing condition.
A test can execute an authorization function without checking whether it rejects the wrong customer. Likewise, processing one valid document tells little about how a parser handles malformed lengths or deeply nested structures.
Some defects also produce no obvious error. An unauthorized data request may return an ordinary success response and leave an ordinary-looking access log. Without relevant identity and ownership context, monitoring may not distinguish misuse from legitimate activity.
Automated tools inspect different parts of the problem
Security tools provide useful evidence, but each observes a limited view of the application.
| Testing approach | What it can help reveal | What it may miss |
|---|---|---|
| Static application security testing | Suspicious code patterns and unsafe data flows | Business rules or runtime behavior it cannot model |
| Dynamic application security testing | Observable weaknesses in a running application | Unreachable workflows, unusual roles or complex application states |
| Software composition analysis | Known issues associated with identified dependencies | Undisclosed defects or whether an affected path is actually reachable |
| Fuzz testing | Unexpected behavior triggered by generated or mutated inputs | Workflows and interfaces outside the test harness |
| Manual security review | Authorization gaps, trust assumptions and workflow abuse | Paths the reviewer does not examine |
Finding more vulnerabilities requires complementary methods, not simply running the same scanner more often. A dependency scanner cannot infer that customers must never access another tenant’s records. A reviewer may understand that rule but overlook an obscure file-parsing error that fuzzing exposes.
Authenticated testing also matters. A scanner operating only as an anonymous visitor cannot evaluate most actions available to signed-in users or administrators.
Heartbleed shows how a small check can have a large impact
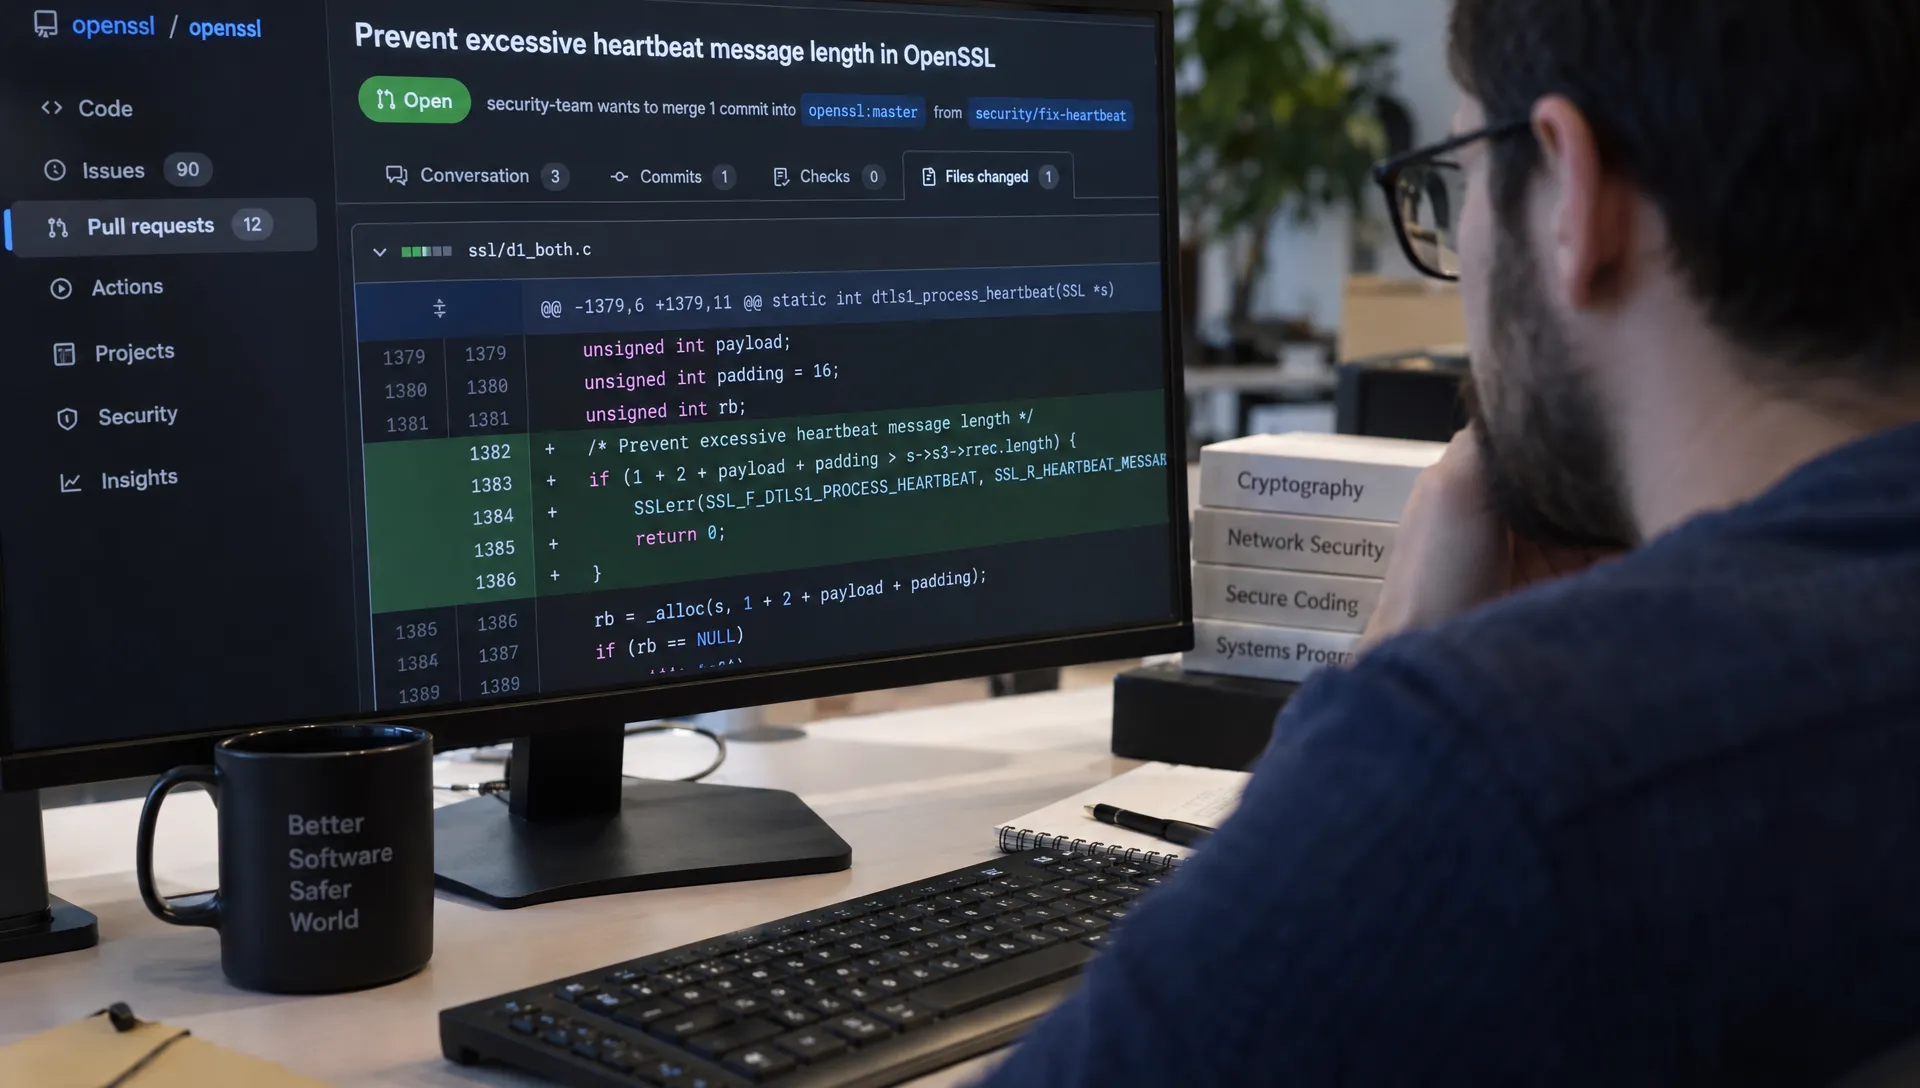
Heartbleed, tracked as CVE-2014-0160, provides a concrete example. The flaw affected OpenSSL’s implementation of the TLS heartbeat extension. A missing bounds check allowed a crafted request to cause the program to return memory beyond the supplied message.
The Heartbleed disclosure site documents that the affected code entered OpenSSL in 2012 and the issue became public in April 2014. Depending on what was present in memory, exposed data could include sensitive information such as credentials or cryptographic material.
The lesson is not that every parser defect has the same consequences. It is that successful normal operation does not prove safe handling of adversarial input. Valid encrypted connections could work while a separate input-handling path remained unsafe.
This example illustrates how a small implementation oversight can have consequences far beyond the function containing it.
Why discovered flaws can remain unnoticed inside an organization
Public disclosure and local awareness are different milestones. A vendor can publish an advisory while an organization remains unaware that an affected component exists in its environment.
Asset inventories may omit an old appliance, a nested dependency or a container image deployed by another team. Product names and package versions may also differ between procurement records, build systems and scanner results, making affected software difficult to match reliably.
Ownership gaps add delay. The application team may expect infrastructure staff to patch a component, while infrastructure staff regard it as part of the application. Neither group has a complete picture of responsibility.
Even acknowledged vulnerabilities can remain exposed when a patch breaks compatibility or requires a difficult maintenance window. Temporary controls may reduce exposure, but they need verification and an expiration plan.
Prioritization should account for evidence of exploitation, exposure, required privileges and business impact. The CISA Known Exploited Vulnerabilities Catalog is useful evidence of exploitation in the wild, although absence from the catalog is not proof that a flaw is safe to defer.
How teams can shorten the detection gap
The practical goal is to challenge assumptions earlier and make affected systems easier to identify later. Buying another tool helps only if its findings connect to an owner, a decision and a verified fix.
A focused approach includes:
- Write explicit security rules: Define who may access each resource, which operations require elevated privileges and which data must remain separated between customers.
- Test rejection paths: Verify that the application denies unauthorized identities, invalid state transitions and unexpected input, not just that valid requests succeed.
- Match testing to the component: Use parser-focused fuzzing for complex input formats, role-based testing for authorization and dependency analysis for third-party components.
- Maintain component ownership: Record deployed versions and responsible teams so an advisory can be mapped to real systems rather than an incomplete spreadsheet.
- Verify remediation: Confirm the fix is deployed, retest the original failure condition and check for the same pattern in related code.
These practices help teams discover vulnerabilities before an incident and reduce the time between disclosure and remediation. They also make findings more actionable: a reproducible failure tied to a specific security rule is easier to investigate than a vague warning.
The NIST Secure Software Development Framework provides a broader foundation for integrating security into development. The useful shift is to treat security as part of design, implementation and maintenance rather than as a final scan before release.
Frequently asked questions
Can a security flaw exist for years without being exploited? Yes. Exploitation may require unusual access, a specific configuration or a technique nobody has identified publicly. However, a lack of observed attacks does not establish that exploitation has never occurred, especially when logging is incomplete.
Is a zero-day necessarily a newly written bug? No. The term concerns the flaw’s discovery, disclosure or available defenses, not the age of the code. An issue described as a zero-day may have existed in a product for years before anyone recognized its security consequences.
Does a high CVSS score prove attackers are exploiting a flaw? No. CVSS describes severity characteristics, not evidence of active exploitation. When prioritizing vulnerabilities, combine severity with the affected system’s exposure, business importance and available threat intelligence.
Put new disclosures in context
When a new security advisory appears, ask three questions: what assumption failed, where does the affected component exist and what evidence confirms the fix? Those questions turn a headline into a practical investigation. Follow CyberSecurityWaala’s cybersecurity news coverage to stay informed about new disclosures and exploitation reports.
About the Author



